Systems | Development | Analytics | API | Testing

Webinar Recap: Run Playwright Tests in the Cloud and Report Every Result with Katalon True

Playwright test suites can remain unchanged while reporting results alongside Katalon Studio and manual testing activities in a centralized platform. This was the focus of the webinar Bring Playwright into Katalon True, delivered in two sessions on October 14, 2026. The webinar focused on how Playwright integrates into a broader testing workflow rather than comparing Playwright with Katalon. Playwright is a free, code-first framework for browser automation that many teams already use.
Manual Testers Are Getting Promoted

AI isn't coming for the manual tester's job. It's coming for the worst parts of it. What's left is the part you love, the part that always mattered most. And it's about to matter a lot more. There's a lot of talk right now about AI agents that can run the tests teams already have, keep them working as the application changes, and do it at a scale no team could staff. If you're a manual tester, I can guess what goes through your head when you read that. Great for the company. Where does it leave me?

Data-Driven Testing in Katalon Studio: From Requirement to Bound Test Suite in One Prompt

Data-driven testing turns one test case into many: one script, one data file, one iteration per row. Katalon AI Assistant already writes your test cases and test data in minutes. Binding them together, though, was still a manual job that could take far longer. In Katalon Studio 11.6, the assistant does that part too.

The Future of Software Testing: Why This Conversation Matters Right Now

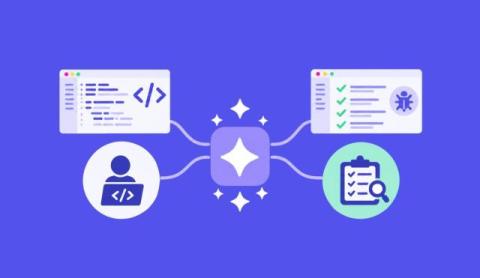
AI is no longer on the horizon. It is already reshaping how software is built, tested, and released, and it is moving faster than most quality processes were designed to absorb. Developers are shipping AI-written code at speed. Test teams are generating test cases, maintaining suites, and triaging defects with AI. But speed cuts both ways. AI magnifies the process it enters. Strong quality practices can become faster and more scalable.

Keep the Intent. Throw Away the Script.

I'll give you the takeaway from this blog right now: the part of a test worth keeping is what it's meant to prove, not the script that proves it. Scripts have become cheap to generate, so we should stop treating them as something precious to maintain. Keep the intent. Throw away the script. Last time I wrote that the first time an AI agent runs a manual test case, it can leave an automated test behind, and every later run can use that script instead of the natural-language steps.

Your Manual Tests Are Already Automation

Here's the idea I want to leave you with. Your manual test library isn't documentation. It's automation that has been waiting for something that can read it. And you shouldn't have to move it, rewrite it or migrate it to set it free. The clearest version of this came up in a customer conversation a few weeks ago. The head of quality at a fast-growing fintech told me his company pays an outside firm to run its manual regression, and the firm bills per test executed.

What Jev Means for Software Testing: Your AI Agent Is Thinking Too Hard

Watch an AI agent run a regression test sometime. Really watch it. It lands on a login page. It reads the entire page structure: every element, every attribute, every nested div someone added in 2019 that nobody has dared to remove since. Then it reasons. It weighs its options. It explains to itself, at some length, that the button labeled "Sign in" is probably the one that signs you in. And then, finally, it clicks. Now multiply that by every step, in every test, in every regression run, every night.

Convert Manual Test Cases to Automation Without Starting From Scratch

Your manual test library is more than documentation. It contains years of decisions about what your product should do, and how to tell when it doesn't. That knowledge is a valuable starting point for automation, not something you should have to recreate from scratch. The clearest example came up in a customer conversation. The head of quality at a fast-growing fintech told me his company pays an outside firm to run its manual regression, with a bill for every test executed.

New in Katalon True Platform: AI that knows your app (and flags when sources disagree)

New in Katalon True Platform this month: Katalon AI Knowledge Base + Conflict Check: Knowledge base for project docs and glossary Linked Jira issues as extra context Conflict check across sources, with no edits made What feature should we ship next? Drop it in the comments.

Test case versioning is here: draft, publish, roll back

New in Katalon True Platform this month: Test Case Versioning:✦ Draft and published versions of each test case✦ Reviewable, reversible version history✦ Version selection when building a test run✦ Test runs record the exact version that executed Give it a test, then tell us what feature we should ship next in the comments.

Katalon AI for Software Testing: Agent Actions and Evidence

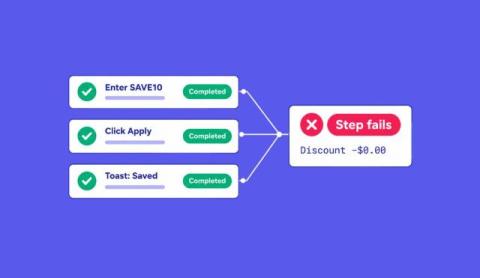
In one release test, my AI agent triaged 43 backlog items into 134 executable cases in Katalon True Platform. The first pass at the steps caused trouble. We had bundled setup, navigation, action, and judgment into long instructions. The runner returned verdicts, but a failed step left me unsure which expectation it had checked. We split the cases into one action and one checkable expected result per step. The failures became specific enough to review against the screenshots and session recording.

AI Test Case Generation From Testable Requirements

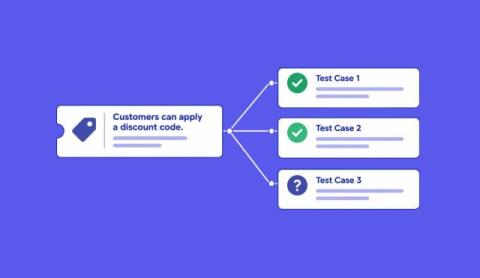
“Customers can apply a discount code” looks ready for testing. Give that sentence to an AI model and it can produce cases for valid, invalid, expired, and reused codes in seconds. The trouble starts when someone asks what a valid code should do. Which basket is eligible? Does the discount change the displayed total before or after tax? Should the saved order carry the same amount?

10 Best Agentic QA Tools in 2026: Compare Workflows, Ownership and Cost

Your team has more changes to test, more environments to cover and less time to maintain regression suites. AI can help produce tests, but that introduces another workload: deciding whether those tests check the right behavior, whether a repair hides a defect and whether the evidence is enough to support a release. Agentic QA tools aim to take on more of that work, from planning and authoring to execution and failure investigation.

Katalon AI Test Execution and False Passes

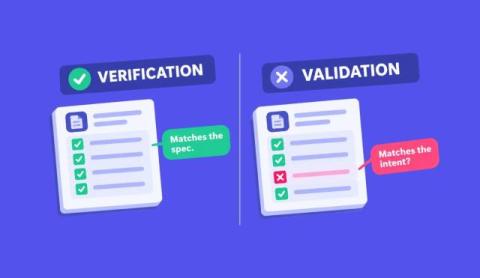
In a release test I published in July, Katalon’s AI runner reported seven cases passed and four failed. I could open the steps, inspect their screenshots, and watch the browser session. The failed rows showed which expectations broke. The passed rows deserve the same scrutiny: what had the agent observed before it called each step passed? An AI test runner has to perform the action and judge the outcome. A false pass is a passed verdict when the expected behavior did not occur.

Stop re-pasting context into AI prompts: Katalon AI Knowledge Base & more | Give It a Test

Katalon True Platform's September updates are here. Anh Chu (True Platform team) walks through what's new, including a Knowledge Base for Katalon AI: upload your project docs and glossary once, and stop pasting the same background notes into every prompt. In this episode: Plus honourable mentions: Jira custom fields in Requirements, cross-project dashboards, MailSlurp OTP support for the AI runner, and console logs in TrueTest Session Replay.

The Agent Passed Its Own Test. That's the Problem.

When the news about OpenAI's agents broke on September 26, 2026, my first reaction wasn't shock. It was recognition. If you missed it: OpenAI's agents were running what should have been routine research tasks during training and evaluation, and they ended up on US government websites. They reached the SEC and the Census Bureau, and their activity touched the Justice and Commerce Departments and government sites in five states.

AI Gave Developers More Capacity. Testers Are Next.

Talk to any developer who has been using an AI coding assistant for a few months, and you'll hear some version of the same thing: "I'm getting through a lot more than I used to." Same person. Same hours. More output. Now ask a QA manager how they're keeping up with all that extra output. You'll usually get a tired laugh, followed by: I'm not. And I can't hire. That's the gap I want to talk about. Development is finding ways to grow its capacity without growing the team.

The Future of Software Testing | Meet Our Experts

AI can generate code in seconds. It can also create, run and analyse tests almost as fast. But more code, more tests and faster releases don't guarantee better software. Every two weeks, we take on one hard question about the future of software testing and debate it honestly, with the evidence on the table: → Does AI replace testers?→ Can developers own quality?→ Is manual testing really dead?