Systems | Development | Analytics | API | Testing

Building Streaming Data Pipelines, Part 1: Data Exploration With Tableflow

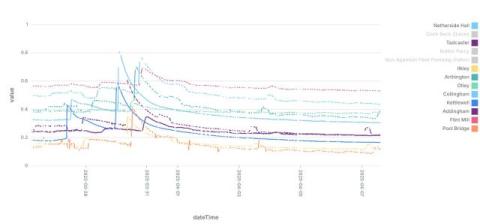
Whether we like it or not, when it comes to building data pipelines, the ETL (or ELT; choose your poison) process is never as simple as we hoped. Unlike the beautifully simple worlds of AdventureWorks, Pagila, Sakila, and others, real-world data is never quite what it claims to be. In the best-case scenario, we end up with the odd NULL where it shouldn’t be or a dodgy reading from a sensor that screws up the axes on a chart.
From Reactive to Orchestrated: Building Real-Time Multi-Agent AI With Confluent

We're entering a new era of artificial intelligence (AI), where intelligence isn't just reactive; it's orchestrated. At Agent Taskflow, we're pioneering a new class of systems: multi-agent orchestration platforms. These systems empower teams of AI agents to coordinate, think, reason, and act in concert—just like human teams. But building these systems at scale requires something most AI platforms overlook: real-time, observable, fault-tolerant communication.

3 Strategies for Achieving Data Efficiency in Modern Organizations

In today's digital age, organizations are experiencing an unprecedented increase in data generation. In 2010, the world stored about two zettabytes of data, and this number is expected to hit 175ZB in 2025. This immense growth underscores the importance of data efficiency in modern organizations. Data efficiency ensures that data is stored, processed, optimized for performance, and managed—cost effectively.

Agencies Win With Data Streaming: Evolving Data Integration to Enable AI

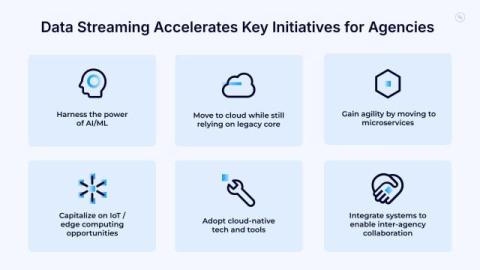
With data streaming, public sector organizations can better leverage real-time data and modernize applications. Ultimately, that means improving the reliability of services that agencies and citizens depend on, enhancing operational efficiency (therefore cutting costs), and delivering critical insights the moment they’re needed.

Guide to Consumer Offsets: Manual Control, Challenges, and the Innovations of KIP-1094

Consumer offsets are at the heart of Apache Kafka's robust data handling capabilities, as they determine how data is consumed, reprocessed, or skipped across topics and partitions. In this comprehensive guide, we delve into the intricacies of Kafka offsets, covering everything from the necessity of manual offset control to the nuanced challenges posed by offset management in distributed environments.

Beyond Boundaries: Leveraging Confluent for Secure Inter-Organizational Data Sharing

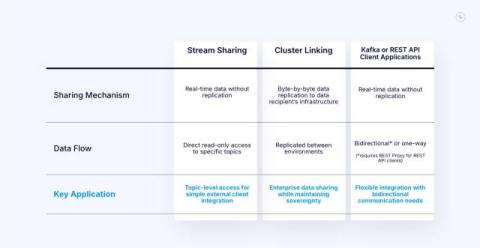
Data is one of a company’s most valuable assets. Its value is often limited, however, by the challenge of sharing it across organizational boundaries in a secure, reliable, and scalable way. Traditional approaches to inter-organizational data sharing have contributed to this. Flat file sharing, API calls, and proprietary solutions all pose different challenges, from security concerns to scalability and development burden.