Systems | Development | Analytics | API | Testing

API + AI Summit 2026 Recap: Helping the World Move AI

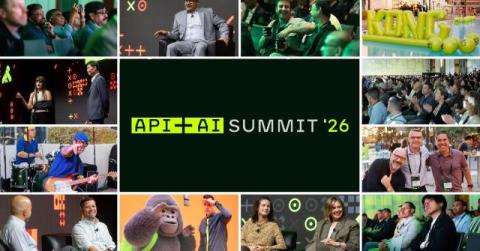
That's a wrap on API + AI Summit 2026, Kong's biggest in-person event yet. The event brought together more than 1,000 engineers, architects, and leaders in Los Angeles to discuss running AI systems in production, tackle shared architecture challenges, and swap real-world insights. Recordings from this year’s event will be available in the coming weeks..
How to Manage and Secure AI Coding Agents

AI coding tool spend is projected to top $13 billion in 2026, compounding at more than 60% a year. These agents don't just autocomplete a line of code anymore. They plan. They act. They call tools, run commands, and touch other systems on your behalf. This is pretty different from the assistant that used to live in your IDE sidebar. And that's exactly where the risk lives. An AI coding agent is software that writes, tests, and ships code independently. This level of autonomy earlier tools never had.

Spot flaky tests and failure trends with agentic QA | SmartBear BearQ

Wondering which of your AI-driven tests need attention right now? Watch this video to learn how SmartBear BearQ spots flaky tests and failure trends the moment they happen, so you always know exactly where to focus. Each report summarizes what happened and surfaces the issues BearQ detected, whether while exploring your app or running a scheduled test. Drill into failed tests to see exactly which runs broke and why, track trending results over time, and review open issues found across both passing and failing runs.

Katalon AI for Software Testing: Agent Actions and Evidence

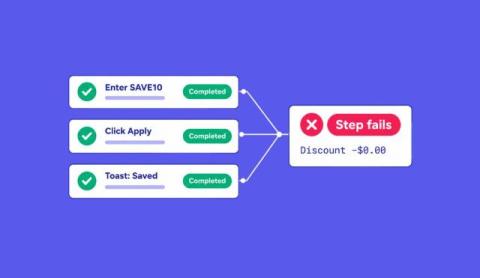
In one release test, my AI agent triaged 43 backlog items into 134 executable cases in Katalon True Platform. The first pass at the steps caused trouble. We had bundled setup, navigation, action, and judgment into long instructions. The runner returned verdicts, but a failed step left me unsure which expectation it had checked. We split the cases into one action and one checkable expected result per step. The failures became specific enough to review against the screenshots and session recording.

AI Test Case Generation From Testable Requirements

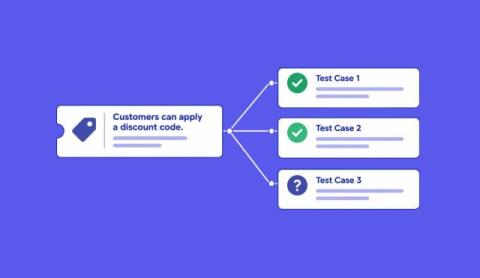
“Customers can apply a discount code” looks ready for testing. Give that sentence to an AI model and it can produce cases for valid, invalid, expired, and reused codes in seconds. The trouble starts when someone asks what a valid code should do. Which basket is eligible? Does the discount change the displayed total before or after tax? Should the saved order carry the same amount?

Introducing Kong Bot Detector: Native API Bot Detection for Dedicated Cloud Gateways

Bots make up more than a third of internet traffic, and API endpoints attract more of it than web pages do. Scanners hunting for.env files, credential-stuffing scripts, LLM training crawlers, and the long tail of low-effort probes all hit your gateway before they ever reach a service. Every one of those requests costs you — in upstream load, in noise across your analytics, and in the bill.

Strategic ROI Frameworks for AI-Driven Quality Engineering

Enterprise software organizations allocate most of their total IT budgets to software validation and quality maintenance. According to the Consortium for Information and Software Quality (CISQ), poor software quality drains over $2.41 trillion annually from the US economy in operational failures, technical debt, and unmitigated production incidents.

10 Best Agentic QA Tools in 2026: Compare Workflows, Ownership and Cost

Your team has more changes to test, more environments to cover and less time to maintain regression suites. AI can help produce tests, but that introduces another workload: deciding whether those tests check the right behavior, whether a repair hides a defect and whether the evidence is enough to support a release. Agentic QA tools aim to take on more of that work, from planning and authoring to execution and failure investigation.

Katalon AI Test Execution and False Passes

In a release test I published in July, Katalon’s AI runner reported seven cases passed and four failed. I could open the steps, inspect their screenshots, and watch the browser session. The failed rows showed which expectations broke. The passed rows deserve the same scrutiny: what had the agent observed before it called each step passed? An AI test runner has to perform the action and judge the outcome. A false pass is a passed verdict when the expected behavior did not occur.