We collect the latest Development, Anaytics, API & Testing news from around the globe and deliver it direct to your inbox. One email per week, no spam.
Is agentic AI testing more hype than substance? Clarifying what this category of software testing actually is, how it works in practice, and where it still falls short.
When business questions move faster than answers, teams need more than dashboards. They need AI agents that can break silos, add context, and turn trusted enterprise data into action. Meet Snowflake CoCo — built to help data teams and business users move from reactive reporting to strategic action. In the Agentic Enterprise, everyone can become a strategic force, shaping what the business does next.
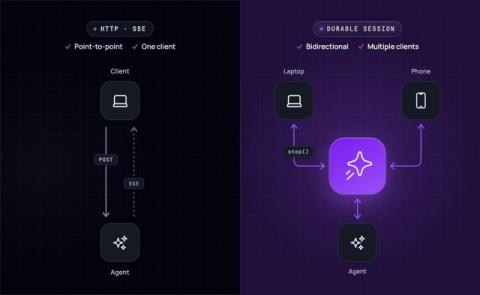
You've built an AI chat app on the Vercel AI SDK. It works in development. The model responds, the stream comes through, and the UI updates cleanly. Then you ship to production, and the transport layer starts showing its edges. Most of these failures are quiet: things that work in demos and break in ways that are hard to pin down until you know where to look. They share a common cause: DefaultChatTransport is built for HTTP, and HTTP has structural properties that some production requirements exceed.
In this guest post, Intellyx Principal Analyst Jason English explores what it takes to level up quality engineering in the age of agentic AI, and why visibility, context, and governance are the keys to getting there. One day in an agentic developer’s life: Developer “CodeBud agent, create me a suite of test cases to validate the feature you just built.” CodeBud Done. Test suite created.
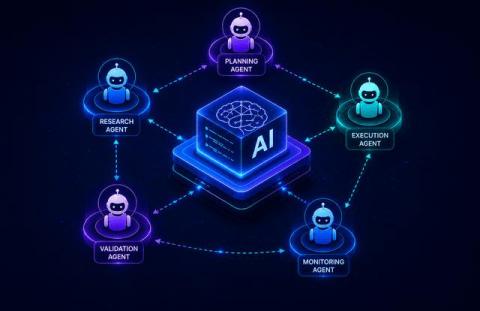
The conversation around AI validation has rapidly outgrown simple prompt engineering and single-turn model checks. While the industry spent the last few years establishing baseline protocols for individual AI agent testing, enterprise automation has already advanced to the next engineering frontier: the Multi-Agent System (MAS).
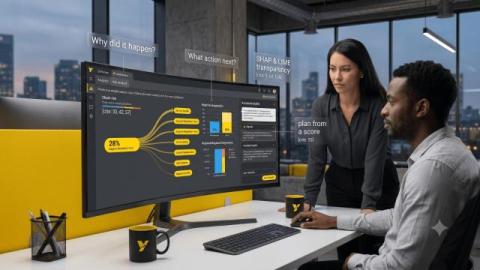
Predictions alone are no longer enough. A churn score is not useful if no one trusts it, and a risk score does not help if the next step is unclear. The same goes for a recommendation engine. People need to know why a model made a call, and what action comes next. That is the core shift in explainable AI for analytics. The work has moved from “what happened?” to “why did it happen, and what should I do now?” Customer-facing analytics depends on that shift.
Running production LLM inference on a new accelerator family is a layered problem. The model matters. The runtime that exists for the GPU you have matters at least as much. So does the precision mode that works without losing accuracy, the inference engine that hits your throughput targets, and the secure endpoint the rest of your stack can actually call. The entire stack underneath the model is where most of the real engineering work lives and where the cost of getting it wrong shows up first.
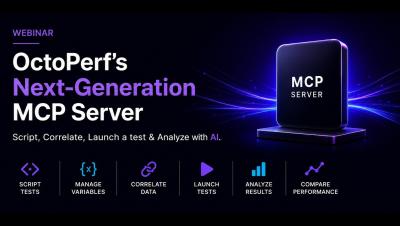
This innovation acts as a true accelerator for performance testing. Connected to your favorite LLM (ChatGPT, Claude, Gemini, Mistral, or a local model), it enables you to manage an entire testing campaign end-to-end using natural language: script creation and maintenance, automatic correlation, load configuration, test execution, results analysis, and optimization recommendations.
I asked Claude what the cash position would be at year-end. The answer was about 30% off. A CFO said this at a finance leaders breakfast in Prague. Almost every CFO in the room had a version of the same story. The problem is not the model. Claude is not bad at maths. The problem is what the model was reasoning over - raw financial data with no governed definitions, no intercompany rules, no agreed methodology for what 'cash position' means at that specific company.