Building an automated data pipeline from BigQuery to Earth Engine with Cloud Functions

Over the years, vast amounts of satellite data have been collected and ever more granular data are being collected everyday. Until recently, those data have been an untapped asset in the commercial space. This is largely because the tools required for large scale analysis of this type of data were not readily available and neither was the satellite imagery itself. Thanks to Earth Engine, a planetary-scale platform for Earth science data & analysis, that is no longer the case.

Analyzing satellite images in Google Earth Engine with BigQuery SQL

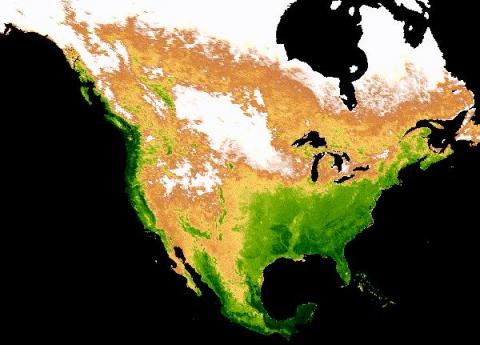
Google Earth Engine (GEE) is a groundbreaking product that has been available for research and government use for more than a decade. Google Cloud recently launched GEE to General Availability for commercial use. This blog post describes a method to utilize GEE from within BigQuery’s SQL allowing SQL speakers to get access to and value from the vast troves of data available within Earth Engine.

How to simplify and fast-track your data warehouse migrations using BigQuery Migration Service

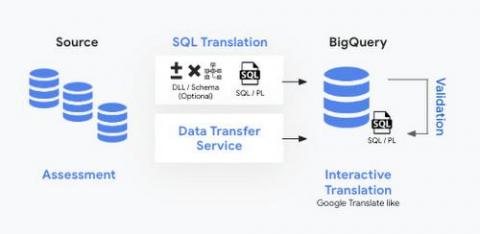
Migrating data to the cloud can be a daunting task. Especially moving data from warehouses and legacy environments requires a systematic approach. These migrations usually need manual effort and can be error-prone. They are complex and involve several steps such as planning, system setup, query translation, schema analysis, data movement, validation, and performance optimization.

Scaling Kafka Brokers in Cloudera Data Hub

This blog post will provide guidance to administrators currently using or interested in using Kafka nodes to maintain cluster changes as they scale up or down to balance performance and cloud costs in production deployments. Kafka brokers contained within host groups enable the administrators to more easily add and remove nodes. This creates flexibility to handle real-time data feed volumes as they fluctuate.

Editing and saving a dashboard

In this video you will learn how to edit one of your existing Yellowfin dashboards — such as adding a new report to a dashboard and then save those edits by publishing the dashboard. You will also learn how to edit/change the title of the dashboard, select/change the folders where the dashboard will be saved, and how to add tags to your dashboard. You will also learn how to edit/change the Dashboard Access to either Public or Private.

A Guide to Principal Component Analysis (PCA) for Machine Learning

Principal Component Analysis (PCA) is one of the most commonly used unsupervised machine learning algorithms across a variety of applications: exploratory data analysis, dimensionality reduction, information compression, data de-noising, and plenty more. In this blog, we will go step-by-step and cover: Before we delve into its inner workings, let’s first get a better understanding of PCA. Imagine we have a 2-dimensional dataset.

7 Best Change Data Capture (CDC) Tools of 2022

As your data volumes grow, your operations slow down. Data ingestion - extraction of all underlying datasets, transformation, and loading in a storage destination (such as a PostgreSQL or MySQL database) - becomes sluggish, impacting processes down the line. Affecting your data analytics and time to insights. Change Data Capture (CDC) makes data available faster, more efficiently, and without sacrificing data accuracy. In this blog we are going to overview the 7 best change data capture tools of 2022.