Systems | Development | Analytics | API | Testing

WSO2 AI Gateway: Prompt Management & Semantic Caching

Learn how to ensure consistent AI interactions and drastically reduce latency using the WSO2 AI Gateway. This step-by-step tutorial demonstrates how to standardize your LLM requests for quality and efficiency while cutting down on redundant API costs. We explore "Prompt Management" to enforce organizational guidelines using templates and decorators, and "Semantic Caching" to leverage vector embeddings—serving instant, cached responses for semantically similar queries to minimize expensive LLM calls.
The Breakdown | API calls and mobile apps

You used an API this morning. Probably before you even got out of bed. That weather app? It's your phone communicating with a server in the cloud — sending a request, getting data back, and displaying it on your screen in seconds. Location. Request format. Expected response. That's the anatomy of an API call. And it's happening constantly across nearly every app on your phone. Hugo Guerrero and Amanda Alcamo break it all down in Episode 2 of The API & AI Breakdown. No jargon. No fluff. Just clarity.

AI Input vs. Output: Why Token Direction Matters for AI Cost Management

In the burgeoning intelligence economy, AI tokens are a metered utility, but enterprise profitability now hinges on a critical distinction: output tokens can cost up to 10x more than inputs, creating a new, invisible risk for cost overruns, particularly with Agentic AI. Learn how Kong AI Gateway and Konnect Metering & Billing provide the essential financial control plane to enforce directional guardrails, protect margins, and turn token consumption into realized revenue.

Stop GenAI Rate Limits: Model Routing & Token Throttling with WSO2 AI Gateway

Learn how to mitigate skyrocketing AI costs and prevent model outages using the WSO2 AI Gateway. This step-by-step tutorial shows you how to move beyond simple request limits and implement smart, token-based usage policies. We also demonstrate "Adaptive Model Routing" showing you how to automatically switch between models when rate limits are hit, and how to distribute traffic using weighted round-robin to optimize for cost and performance.

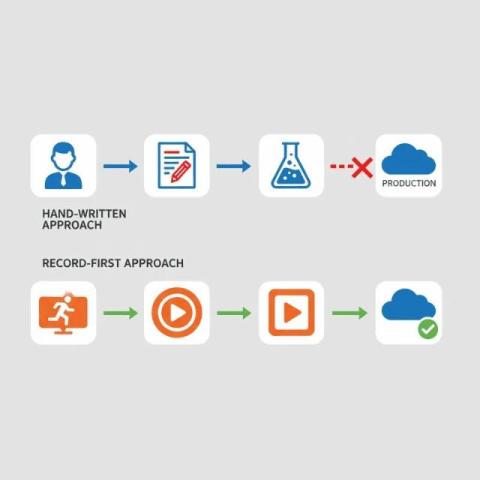
WireMock vs MockServer vs proxymock for API testing

Your WireMock stubs are lying to you. They were accurate when someone wrote them six months ago, but the payment API added a metadata field in January, the inventory service switched from REST to gRPC in February, and nobody updated the stubs because the tests still pass. Meanwhile, production is breaking in ways your mocks will never catch. This is not a WireMock problem. It is a hand-written mock problem.

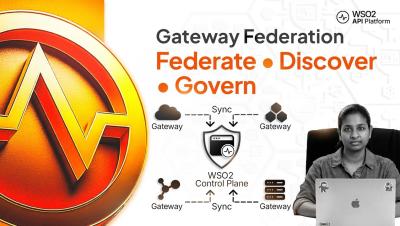
Gateway Federation with WSO2 API Manager

In this hands-on screencast, we walk through how to implement Gateway Federation using WSO2 API Manager. Modern enterprises often operate multiple API gateways across environments, business units, regions, or subsidiaries. Managing and governing APIs across these distributed gateways can quickly become complex and inconsistent. *In this video, you’ll learn* : If you're building a distributed API ecosystem and need centralized governance without losing flexibility, this video is for you.

Connect API design, testing, and governance in one workflow | Swagger

API design, functional testing, and governance shouldn’t live in silos. In this demo, Product Owner Wojciech Nowacki walks through a practical, end-to-end workflow that connects: You’ll see how API definitions created in Studio feed directly into automated functional testing ensuring style compliance, functional correctness, and governance checks across the full API lifecycle. Perfect for API platform teams, architects, and developers looking to unify design and test automation.

Governing Claude Code: How To Secure Agent Harness Rollouts with Kong AI Gateway

The AI coding and Agent Harness approach is no longer experimental. This is likely the most impactful agentic AI use case in production today, and Claude Code is one of the solutions really leading the charge. But as engineering teams race to adopt Claude Code across their organizations, a critical question emerges: who's governing all that LLM traffic?

How Gateway Federation Brings Order to Chaos in Your API Ecosystem

As organizations grow, so does API sprawl. Different teams deploy different gateways. Business units run isolated API stacks. Regions operate independently. The result? Fragmentation, duplicated effort, inconsistent governance, and reduced visibility. *In this video, we explain*: If you're managing APIs across multiple environments and want clarity, control, and scalability — this is where to start.