Systems | Development | Analytics | API | Testing

Bridging the Gap Between Reliable APIs and Unpredictable AI

APIs and AI are on a collision course. For decades, APIs have been the foundation of digital reliability: deterministic systems where you send a request, get a predictable response, and trust that what’s defined is what will happen. AI doesn’t play by those rules. Large language models and AI agents operate in probabilities. They don’t just follow contracts; they interpret them. They learn, infer, and sometimes hallucinate.
How to Test Your AI Apps and Features: A Comprehensive Guide for QA Leaders

Your CEO just announced the company’s AI-first strategy and the product team is shipping AI features faster than ever. Marketing is promising intelligent automation to customers, while the QA team is left wondering how to actually test this stuff. Every QA team is grappling with the same challenge as AI becomes the default solution for everything from customer service to content generation.

Metrics That Matter for Agentic Testing

Traditional test metrics like automation %, pass/fail rates, and defect counts don’t reflect the impact of introducing agents into the QA process. This blog explores a new class of KPIs designed to measure how well your virtual test team is performing including Agent Assist Rate, Human Override Rate, Scenario Coverage Delta, and Review Time Saved.

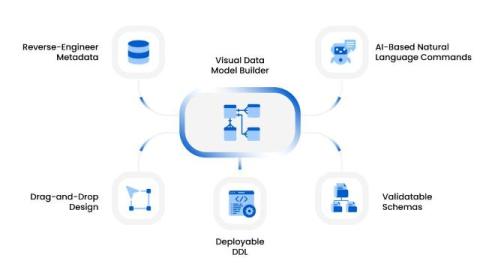
AI-Powered Data Modeling: From Concept to Production Warehouse in Days

Key Takeaways Enterprise data teams spend millions on warehouse infrastructure while still designing schemas the way they did in 1995—one entity at a time, one relationship at a time, hoping the model survives its first encounter with production data. The irony runs deep: organizations racing to deploy real-time analytics are bottlenecked by modeling processes that take six to eight weeks before a single pipeline runs. Data warehouses succeed or fail on design.

Why Fast Analytics Unlocks Smarter Decisions (and AI Readiness)

A few years ago, we looked across many deployments and noticed a pattern: teams would build prototypes, spin up ML pipelines, and then stall. The model’s accuracy dropped. The “aha insights” dried up. The data scientists would get stuck waiting for dashboards to refresh, or data to be cleaned.AI is sexy. It sells. But it doesn’t do itself. The missing piece? Data readiness. Not just fast data.

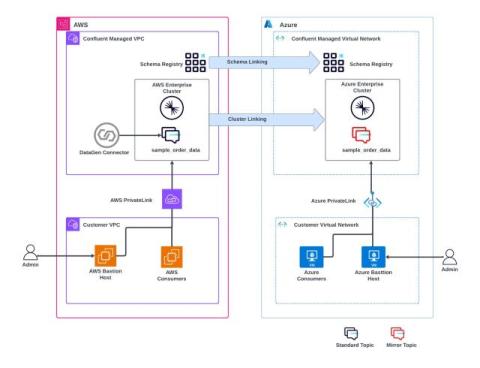
Cross-Cloud Data Replication Over Private Networks With Confluent

Modern businesses don’t run in just one place. Your applications might live in Amazon Web Services (AWS), your analytics in Microsoft Azure, and critical systems on-premises. The challenge? Keeping all that data connected and flowing in real time—without adding complexity or risk. As more organizations adopt these multicloud strategies, the need for secure, private data replication has become critical.

The True Cost of Kafka Replication

Kafka cluster-to-cluster data replication is critical to many use cases: disaster recovery (DR), cloud or data center migration, testing applications with production-like data, and multi-region data distribution. Easy replication of data between clusters: The business case is clear, but the cost model is not. Some solutions appear free but impose heavy operational burden.