Systems | Development | Analytics | API | Testing

Top ESG Software Companies for US Sustainability Reporting in 2026

Ask a sustainability team what slowed their last disclosure and the answer is usually mundane: inconsistent units, missing supplier records, emission factors applied three different ways across four business units, and no audit trail explaining why a number changed between drafts.
What five QE orgs got right about AI transformation

Not all AI transformations are equal, but when AI works well in quality engineering, the results are hard to ignore: 65% fewer major incidents, AI-generated test volume growing 6-7× in a year, or a five-step manual process replaced by three automated workflows. These are just a few of the outcomes from companies that moved past scattered AI experimentation to quality engineering that runs on a continuous, organization-wide signal.

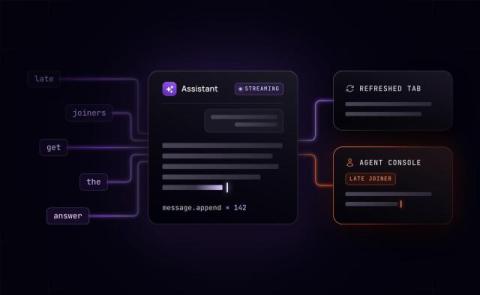
A token is not a message: stop storing AI responses like event logs

How you store a streamed AI response decides what a client sees when the client joins partway through. A human agent taking over a support conversation, a refreshed browser, and a second device all need the response generated so far, and depending on how the response was stored, that late joiner gets the full response, fragments, or nothing. This article compares four common ways to store a streamed response, what each one gives a late joiner, and what each one costs your team.

Reducing GitHub reliability risk for tool installs

You’ve probably encountered the online conversations about GitHub’s AI scaling challenges. A lot of the chatter is about how forgiving (or not) users should be to GitHub in light of inexorable traffic increases but also GitHub’s own decision-making. There is certainly irony in the fact that it was a swashbuckling GitHub, against the objections of many open source developers, that pressed Copilot on the industry.

Katalon AI Test Execution and False Passes

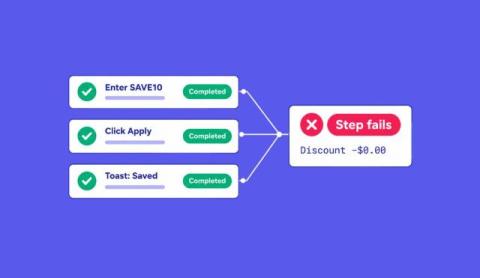
In a release test I published in July, Katalon’s AI runner reported seven cases passed and four failed. I could open the steps, inspect their screenshots, and watch the browser session. The failed rows showed which expectations broke. The passed rows deserve the same scrutiny: what had the agent observed before it called each step passed? An AI test runner has to perform the action and judge the outcome. A false pass is a passed verdict when the expected behavior did not occur.

10 Best Agentic QA Tools in 2026: Compare Workflows, Ownership and Cost

Your team has more changes to test, more environments to cover and less time to maintain regression suites. AI can help produce tests, but that introduces another workload: deciding whether those tests check the right behavior, whether a repair hides a defect and whether the evidence is enough to support a release. Agentic QA tools aim to take on more of that work, from planning and authoring to execution and failure investigation.

Introducing the New Replicate Source for Open Lakehouse

There's a conversation happening in a lot of data teams right now. It goes something like this: the lakehouse is clearly where things are heading, Apache Iceberg is becoming the format everyone wants to land in, and the AI use cases the business is asking for need clean, open, queryable data.

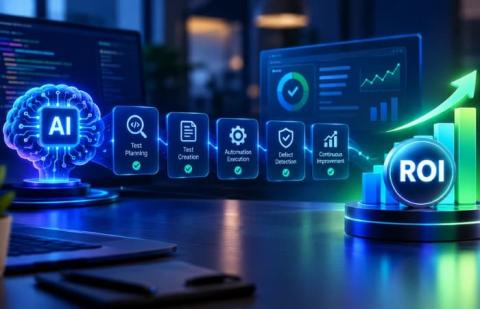
Strategic ROI Frameworks for AI-Driven Quality Engineering

Enterprise software organizations allocate most of their total IT budgets to software validation and quality maintenance. According to the Consortium for Information and Software Quality (CISQ), poor software quality drains over $2.41 trillion annually from the US economy in operational failures, technical debt, and unmitigated production incidents.

Avoid API Rate Limiting: 10 Common Causes

If you want to avoid API rate limiting headaches during load testing, start by proactively monitoring usage patterns. Use real-time metrics to catch spikes before they trigger throttling. Tools like LoadFocus make it easier to visualize these patterns and pinpoint problematic clients or endpoints. Review how you structure requests – batching similar calls together and caching predictable responses can cut down on redundant traffic and ease pressure on the API.