Systems | Development | Analytics | API | Testing

Human Judgment Is the Missing Variable in Your AI Strategy

Across teams, organizations, and industries, people are starting with AI instead of the problem they want to solve. As a result, AI outputs from different tools: This is a process failure, and it's accelerating. Human-in-the-loop (HITL) AI is a framework that integrates human oversight directly into the machine learning lifecycle. Rather than relying on fully autonomous systems, HITL uses humans and machines collaboratively to train models, evaluate outputs, and handle complex decision-making.
Confidence in AI-generated code is rising in lockstep with its failure rate

If you only read the headlines this year, you’d think AI makes shipping good software easier than ever. Yet, this was the year of very public AI-coding incidents. PocketOS’ production database deletion and a Vercel AI agent shipping unverified code are just two examples of AI-authored code shipped with confidence that turned out to be wrong. And, of course, these AI-coding incidents are distinct from Agentic AI orchestration incidents like the HuggingFace hack by OpenAI.

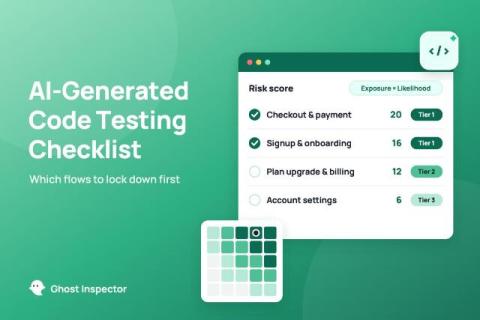
The AI-Generated Code Testing Checklist: Which Flows to Lock Down First

Your developers are shipping more code than ever, and a growing share of it is written by AI. Your QA team, meanwhile, is probably the same size it was a year ago. You’re not imagining the squeeze. In a recent survey of 300 QA practitioners, 52% said bug volume went up after their developers started using AI, and 58% said their own testing workload grew. Not one of them reported getting extra QA headcount to match.

Ep 93 | When Everyone Has AI, Your Data Sets You Apart

After 23 years in machine learning and data science, Cao Hong has seen plenty of AI projects come and go. His measure of success is simple: did it create value for the business? Recorded at *EVOLVE26* Singapore, this episode of The AI Forecast brings Paul Muller together with Cao Hong, Principal Director of Data Apps at NCS, to explore how organizations can turn AI experimentation into measurable business impact.

How to Build a Self-Service AI Platform Without Losing Control of GPUs, Data, or Security

Most enterprise AI infrastructure conversations land on the same tension. Builders want self-service: instant access to GPUs, a stable endpoint for a model, a notebook, or a fine-tuning run that starts without a ticket. Platform teams want per-team quotas, identity-aware access, audit trails, tenant isolation, and cost attribution they can defend. Both sides are right, and most platforms make you choose between them because self-service and control get layered onto a base that was designed for neither.

From BI to Agentic AI: Why the Dashboards You Built Are the Foundation for Agents

Two questions stall almost every agentic AI rollout: Is it secure? And what is this going to cost us? Both get harder to answer the longer you wait to ask them, and easier to answer than most teams assume. If you've already invested in a robust data analytics platform like Qlik, you're closer to a secure, governed, and cost-effective agentic AI deployment than the market's “rip and replace” narrative suggests.

Honoring Absa: Achieving 96% less test creation time with SmartBear QMetry and SmartBear Reflect

At SmartBear, we’re dedicated to empowering teams by delivering application integrity: continuous, measurable assurance that their software works as intended, even as AI accelerates the SDLC. The AI Test Innovators Award: QMetry + Reflect celebrates customers who are using AI to reimagine how they create, maintain, and manage tests – without sacrificing rigor or reliability.

How to Use ChatGPT Codex in Terminal to Build Your First Tool #aicoding #iosdev #aidevelopment

You don’t need a big app idea to try Codex. A messy Downloads folder is enough. In this beginner walkthrough, you’ll ask ChatGPT to write a prompt in plain language, then paste it into Codex in Terminal to build a simple file organizer. You’ll see how to: The file names and folder contents shown are fictional examples. Your first version doesn’t have to be perfect; you can improve it with follow-up prompts.